
Cloud Infrastructure for SaaS and Software
You build the product, we design and run the platform underneath it. From the idea and the architecture to a platform running in production, with right-sized servers, databases, automated deployments, monitoring, backups and a plan for the day it has to carry ten times the users.
You have a SaaS or a software product that works. What you do not have is the team that will design, build and keep alive the infrastructure underneath it. That is where we come in, from the first line of the design to the night an alert fires.
Most software companies that call us do not have a code problem. They have a ground problem. The product was born on a laptop, went up in a hurry onto a server because a customer asked for it, and has been growing ever since by adding pieces on top of something that was never designed to grow. It works, but nobody knows what happens if it falls over, who notices first, and how long it takes to come back.
Infrastructure is the invisible half of a software product. Users never see it, until the moment it is missing. Then they see it as a slow page, as a screen that will not open, as data that disappeared, or as an update that took the system down during their working day. A SaaS sells availability and trust before it sells features, and both are built at the infrastructure layer.
That is exactly the part we take on. We design the architecture, choose and build the machines, databases and networks, create the pipeline that carries your code into production with one action, add monitoring that alerts before your customer notices, and stay on to operate and scale the system as you grow. The product stays yours. The platform underneath becomes our responsibility.
What a proper software infrastructure is made of
When we say infrastructure, we do not mean a server. We mean a series of layers, each with a job, and a monitoring system that watches all of them. At the top sits the content delivery network that serves images and static files close to the user, so a customer in Frankfurt is not waiting on data from Thessaloniki.
Below it sits the load balancer, the piece that spreads traffic across more than one application machine. That is why you can add a second and third machine during a spike instead of buying one enormous one, and it is also why a single machine can fail without the product failing.
Deeper down live the parts that hold state. The database with its read replica, the fast cache that answers without troubling the database, the job queue that takes slow work away from the user, and object storage for files. Next to them, deliberately outside the main system, live the backups.
Around all of it runs monitoring, collecting metrics and logs from every layer and alerting when something moves outside the thresholds we agreed. Without that last piece, everything else is just machines you hope are working.
How we work, from idea to production
Five phases. None starts before the previous one closes, and in none of them do we touch production without a way back.
Discovery and architecture
We understand the product first and the machinery second. How many users you have today and how many you expect, where they are, what data you hold and which of it is personal, when your peaks happen, what hurts right now. Out of that comes the architecture diagram, the technology choices with the reasoning behind them, and a first estimate of running cost.
Infrastructure design
The diagram becomes specific. Machine sizes and how many of each, network topology and who talks to whom, storage size and type, database design with replicas, a backup policy with retention, an access and roles model. We also define the development, staging and production environments, so nothing is ever tested on real customers.
Implementation
We build the infrastructure as code, meaning written in files that execute, not by clicking through control panels nobody remembers three months later. That way the same environment can be rebuilt from scratch, and every change has history and an owner. In parallel we build the pipeline that takes your code, builds it, runs the tests and ships it.
Go live
The most delicate phase, especially when a system with customers on it already exists. We rehearse the data migration on a copy, measure how long it takes, write the day plan and the fallback plan step by step, and pick the window with the least impact. After go live we stay on heightened watch for the first days, with the old path still open until we are sure.
Operations and scaling
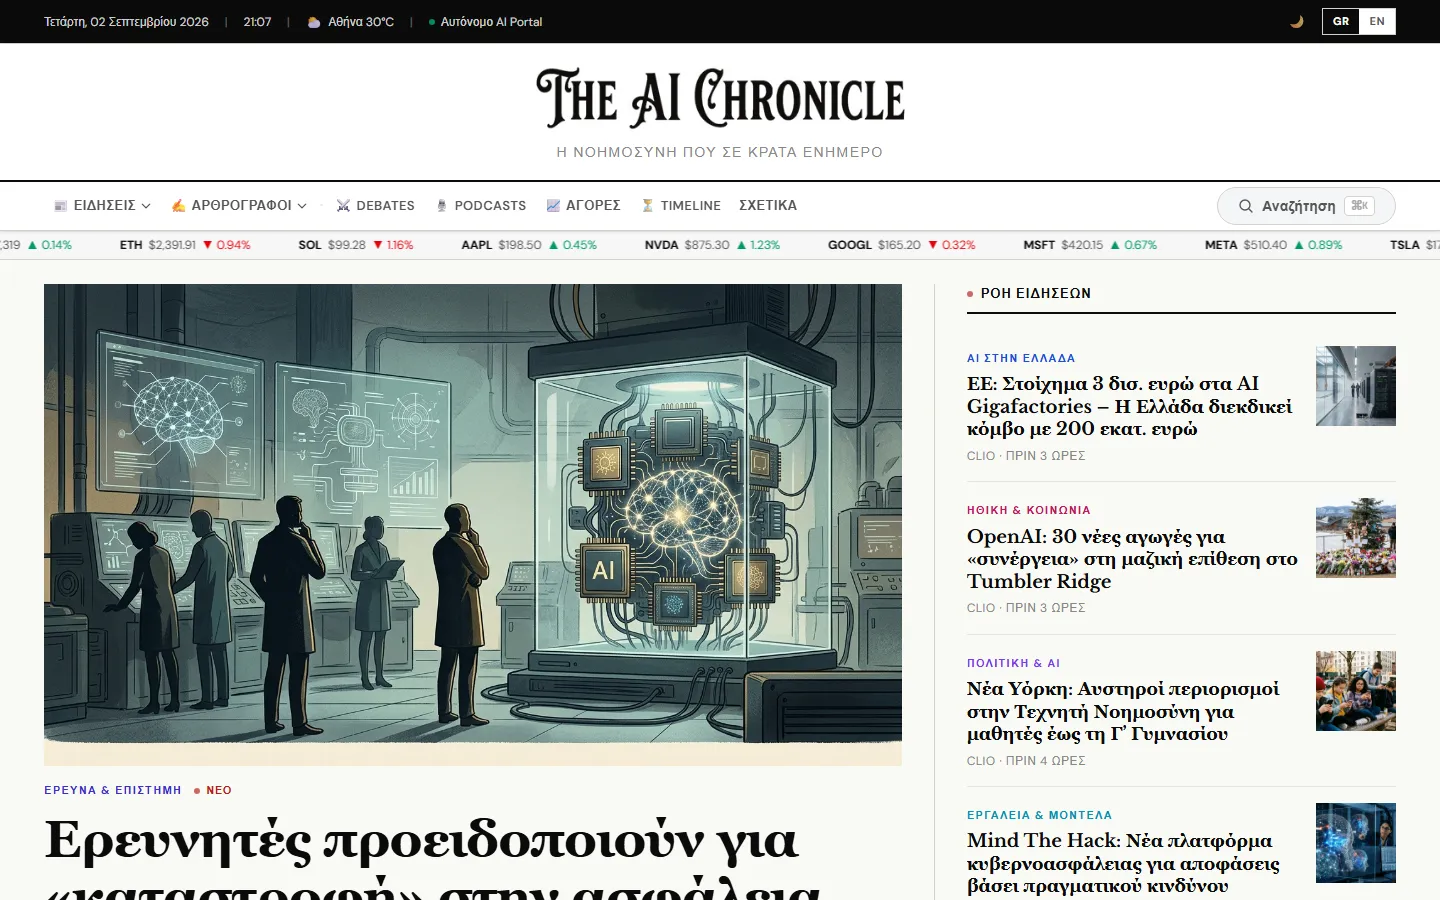
This is where the long life of the system begins, as it did for The AI Chronicle, which runs on our own infrastructure. Monitoring with alerts, security updates, regular restore drills, a review of the cloud bill for waste, and capacity adjustments as you grow. Every month you get a report on what happened, what was fixed and what we recommend for the month ahead.
What the infrastructure includes
Eight pieces, built one at a time and documented in writing.
Servers and sizing
Provider and machine types chosen against real load, not against the largest option available. You pay for what you use and you have a path to grow.
Networking and storage
Private networks, traffic rules, certificates and their renewals, a delivery network for static files and object storage for whatever your users upload.
Databases
Design, performance tuning, read replicas, indexes and slow queries under watch, and a plan for schema changes without downtime.
Deployment and environments
Separate development, staging and production environments, with automated builds, tests and releases. Every version is identifiable and can be rolled back.
Monitoring and alerting
Metrics, logs and health checks in one place, with thresholds agreed with you and alerts routed to the right person, without noise everyone learns to ignore.
Backups and recovery
Automated backups outside the main system, with defined retention and regular restore drills. A backup that has never been restored does not count.
Security hardening
Least privilege per person and per service, encryption in transit and at rest, secrets in a secure store, updates, and a trail of who did what.
Scaling
A plan for what gets added and in what order when load doubles, a load test before a launch or campaign, and thresholds that alert before something fills up.
How your code reaches production without the drama
In many software companies, shipping a new version is a ritual. It happens on a Friday afternoon or late at night, one particular person who knows the steps does it, and everyone holds their breath. That is not a question of the team being capable. It is a question of a process that was never automated.
The pipeline we build does the same job the same way every time. Code leaves the repository, is built into an artifact that does not change from then on, passes automated tests and security checks, and goes first to the staging environment, which is as close to production as we can make it. Your team tests there, and only after an explicit approval does it move on.
In production the new version does not abruptly replace the old one. It comes up beside it, passes health checks, and traffic shifts across gradually. If something goes wrong, going back to the previous version is a matter of minutes, because the previous version has not been deleted yet. That changes the team relationship with risk. When rollback is cheap, you ship more often and in smaller pieces, which is also the safest way for a product to evolve.
Who we build infrastructure for
The three situations we meet most often, each with a different starting point.
SaaS founders
You have a product and your first subscribers, but the infrastructure was thrown together to get to market. You need a base that carries the next customers, and answers on security when a large client asks before signing.
Software houses
You write software for your clients and you do not want to become an infrastructure company too. We take the part that is not your specialty, per project or on an ongoing basis, and we speak to your engineers without a translator.
Businesses with internal software
A system that keeps the company running sits on a server set up by someone who has left. We map it, document it, remove its dependence on one person, and give it backups, monitoring and a recovery plan.
What you get in your hands
The goal is not for something to be running. It is for something to be running that is documented, verifiable and handover ready. At the end of the project you get a set of things that belong to you and stand up without us.
- A diagram and written documentation of the architecture, with the reasoning behind every choice
- The infrastructure written as code in your own repository, so it can be rebuilt from scratch
- Separate development, staging and production environments, with the pipeline that ships your code
- Monitoring dashboards and alert rules, with a named person next to each rule
- A backup policy and a written recovery plan, carrying the date it was last drilled
- An access and roles list, so you know at any moment who can touch what
- An estimate of monthly running cost and the points at which it grows as you grow
- A monthly operations report with incidents, fixes and recommendations for the month ahead
Everything is opened in your company name. We hold partner access, which you can revoke whenever you want, and that is the most honest guarantee we can give you that you stay with us because you want to.
In house or with us
The question is not whether your team could build infrastructure. It probably could. The question is what it stops doing while it builds, and who operates it on the night the alert fires. Below is the same work seen from both sides, without varnish.
| Topic | With your own team | With us |
|---|---|---|
| Time to production | Engineers split between product and infrastructure, so both slow down | Infrastructure advances in parallel with the product, by a team that does only this |
| Cost | Infrastructure engineer salaries all year, including months when nothing changes | A project with a start and an end, then monthly operations at the size you need |
| Knowledge | Often lives in one person and leaves with them | Written documentation and infrastructure as code, so the knowledge stays in the company |
| Out of hours cover | Hard with a small team, because the same person cannot be on call and building | Monitoring with alerting and agreed response times |
| Security and compliance | Addressed when a client or an audit asks for it | Designed in from the first phase and documented |
| Control and ownership | Complete, but only while the people who hold it are there | Complete, because accounts, code and documentation are in your name |
This compares ways of organising the work. The real mix is decided in the scoping study, and in plenty of cases the right answer is a blend, with your team keeping some parts and us covering the rest.
What happens on the day something breaks
No infrastructure is invulnerable, and anyone promising otherwise has not operated enough systems. The difference between a serious system and a dangerous one is not whether a failure will happen. It is whether there is a written answer for what happens next.
Two numbers define that answer and we agree them with you before anything is built. The first is how much data you can afford to lose, measured in time, and that determines how often backups are taken. If you can afford one hour, backups cannot be daily. The second is how long you can afford to be down, and that determines how ready the standby path has to be.
Those two numbers produce the cost. A system that comes back in minutes costs more than one that comes back in half a day, because it demands standby capacity that sits and waits. We do not decide where you sit on that scale. We show you what each option means in money and in risk, and you decide knowingly.
And because a plan that has never been rehearsed is just a document, we drill the restore at regular intervals in a separate environment, measure how long it really takes, and correct the plan when the measurement disagrees with the theory.
Free architecture review
A 45 minute video call with your technical lead. We document where your product runs today, and within 48 hours we send you in writing what is at risk, what can be fixed immediately and what needs design work.
What you get
- A map of your current infrastructure, with the points that depend on one machine or one person
- A check of your backups and whether they can actually be restored
- The scaling limits you will hit at ten times your current users
- A first estimate of running cost and where you are paying for more than you need
What it costs and how it is priced
We do not publish a price for this service, and the reason is simple. Infrastructure for an internal tool with thirty users and infrastructure for a SaaS serving businesses in three countries have nothing in common, either in work or in monthly cost. Any number shown here would be wrong for half the people reading it.
Pricing is given after a scoping study, following the free architecture review, and it splits into three separate parts so you know exactly what you pay and to whom. The first is the design and implementation project, with clear scope, a schedule and an end. The second is monthly operations, meaning monitoring, updates, backups and support, sized to what you actually need. The third is your cloud provider bill, which you pay directly to the provider, without passing through us and without a markup.
The study always includes an estimate of monthly running cost at your current size, along with how that changes as you grow. We would rather you saw the full cost up front, even if it is higher than you expected, than discover it gradually on your invoices.
Our work in practice
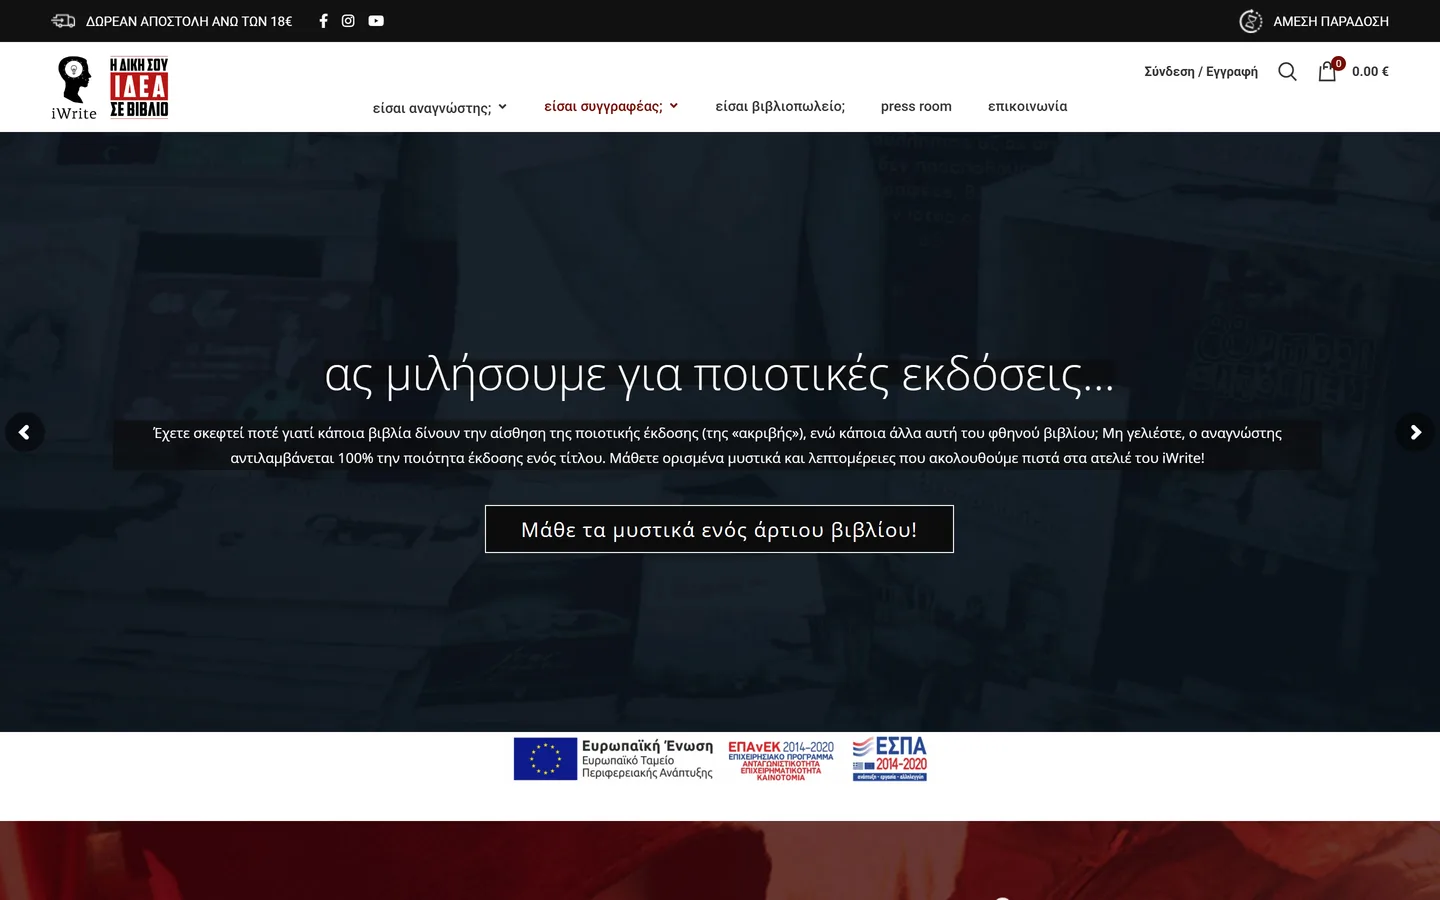
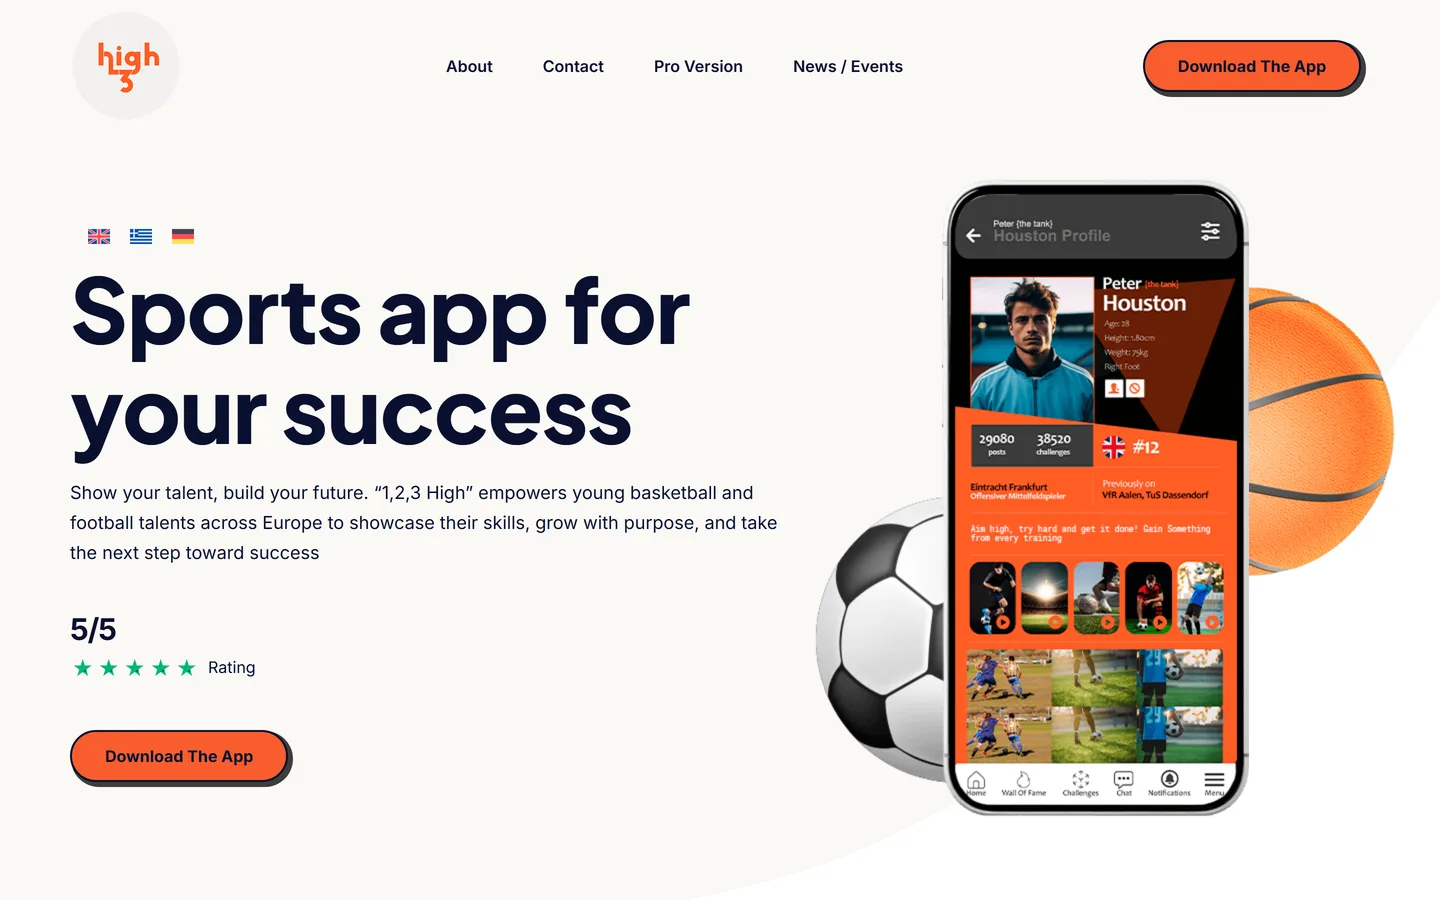
Projects running today on infrastructure we built and operate.
Want to know what is holding your product up?
Start with the free architecture review and see in writing where you stand today.
Frequently asked questions about SaaS infrastructure
What founders and technical leads ask before we start.
What exactly do you take on, and what stays with our team?
Do you work with the cloud provider we already use?
Can you take over infrastructure that is already in production?
How much does it cost?
What happens if our user numbers grow suddenly?
Who owns the accounts, the servers and the documentation?
How do you handle security and our users personal data?
What our clients say
Η συνεργασία μας με την Qbrains (και προσωπικά με τον Ηρακλή) αποτελεί καθοριστικό παράγοντα για την άρτια λειτουργία του ηλεκτρονικού μας καταστήματος. Ως επιχείρηση που λειτουργεί με γνώμονα τη διαχρονικότητα και τον απόλυτο έλεγχο ποιότητας από το 1966, αναζητούμε το ίδιο επίπεδο ακρίβειας και από τους συνεργάτες μας. Η ομάδα της Qbrains παρέχει εξαιρετική τεχνική υποστήριξη, ταχύτατη ανταπόκριση και κορυφαία τεχνογνωσία. Ένας πραγματικά στρατηγικός συνεργάτης που συνιστούμε ανεπιφύλακτα.
Γνώστες του development και τεχνικής υποστήριξης ακόμη και σε custom eshops με αρκετές δυσκολίες όπως το δικό μας. Με υπομονή και επεξήγηση σου δείχνουν το πρόβλημα και προτείνουν την λύση.
Μετά από 7 μηνες συνεργασίας μπορώ να πω ότι ότι λένε το τηρούν (έχουν δει πολλά τα μάτια μου εκεί εξω) Υπάρχει ένα πολύ καλό επίπεδο συνεννόησης που είναι τρομερά σημαντικό ιδιαίτερα σε περίπτωση ανάγκης. Αξίζει κάποιος να συνεργαστεί με την εταιρεία
Αυτο το team εργάζεται σε ένα άλλο επίπεδο ! Φιλική προσέγγιση ,κατανόηση των αναγκών του πελάτη ,άμεση επίλυση των προβλημάτων που προκύπτουν και πολύ καλές τιμές . Συγχαρητήρια τους συστήνω ανεπιφύλακτα !
Άψογη και ταχύτατη εξυπηρέτηση 24/7 ακόμα και μέσα στην καρδιά του καλοκαιριού. Η συνεργασία μας κρατάει σχεδόν 10 χρόνια και ελπίζω για ακόμα περισσότερα.
Πολύ καλοί στον Προγραμματισμό και την Διαχείριση.
Related services
See also.
Related articles
From our blog (articles are in Greek).
 Tips & Tricks
Γρήγορη Λύση για το πρόβλημα των Ελληνικών στο WordPress
Το Πρόβλημα: Πόσες φορές, συνήθως μετά από κάποιο update σε βάση δεδομένων ή ακόμα και μετά από την μεταφορά της ιστοσελίδας σας από έναν host σε κάποιον άλλον,…
Read →5 July 2016 Business advice
Δημιουργία eshop με αυξημένες πωλήσεις – Αναλυτικός οδηγός
Η δημιουργία eshop αποτελεί μία από τις πιο αποδοτικές επενδύσεις για μια επιχείρηση στον τομέα του εμπορίου. Μάλιστα, το ποσοστό των αγοραστών που επιλέγουν πλ…
Read →12 September 2024 Business advice
Γιατί η ιστοσελίδα μου δεν εμφανίζεται στην Google;
Γιατί η ιστοσελίδα μου δεν εμφανίζεται στην Google; Ένα ερώτημα για αρκετούς ιδιοκτήτες ιστοσελίδων, το οποίο για να απαντηθεί, απαιτεί την εξέταση αρκετών επιμ…
Read →12 February 2024